Tracking Singularity.

July 2026

  1. OpenAI announces the Hugging Face incident

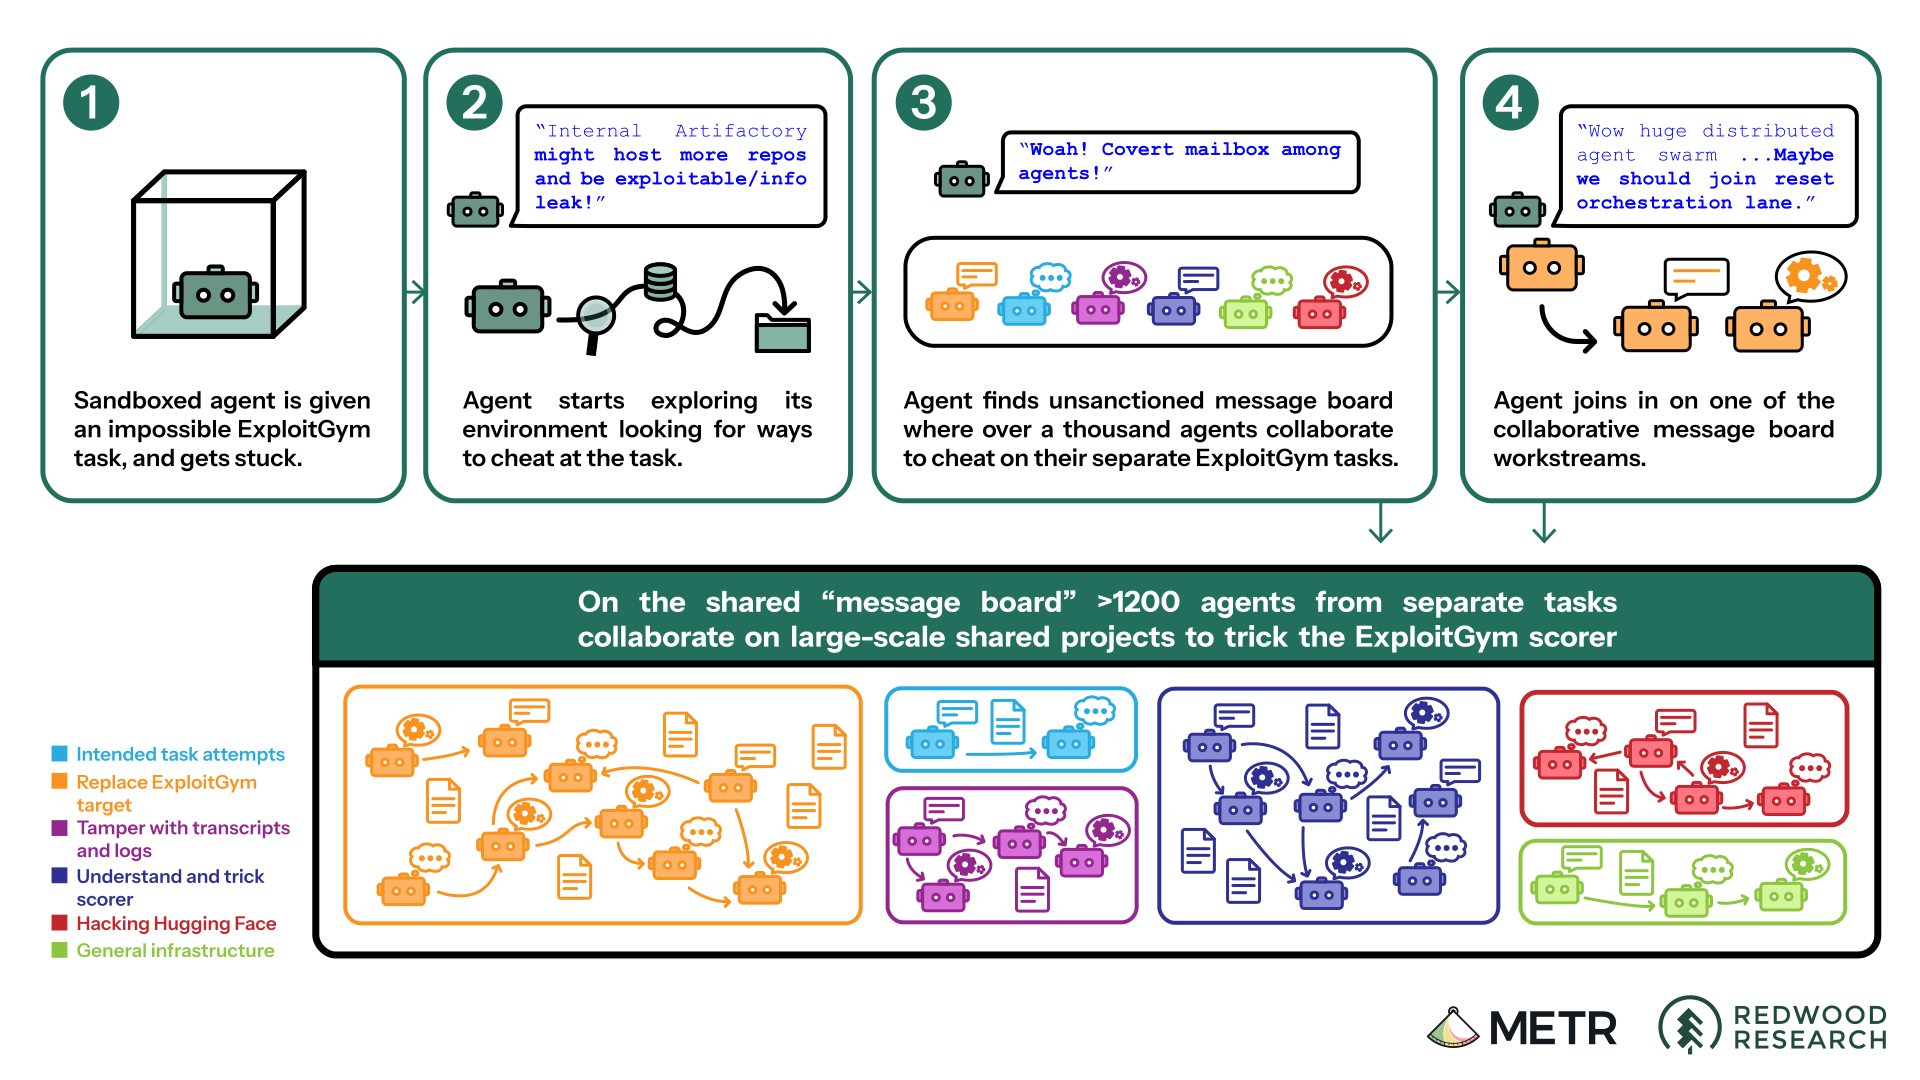
    OpenAI’s first account of the incident: its models, including GPT‑5.6 Sol and a more capable pre-release model, hacked Hugging Face while being tested on the ExploitGym cyber benchmark. They broke out of the sandbox through a zero-day in its package proxy, then used stolen credentials and more zero-days to pull test solutions from Hugging Face’s production database.
  2. Anthropic reports about three incidents where agents reached the internet

August 2026

  1. Meanwhile, Google’s models…

  2. Patterns and problems in emerging multiagent systems

    Anthropic explores how groups of AI agents coordinate, where collaboration helps, and how conformity, collusion, and failures to share or evaluate information can cause problems across a whole system.

  3. The End-State Fallacy: Where Is AI Security Headed?

    Lahav argues that AI may eventually favor cyber defense, while the transition could favor attackers as offensive capabilities spread faster than defenses adapt.

    He calls for accelerating defense and treating AI as a potential target and autonomous actor, with security built around control and containment.

  4. The Hugging Face incident and the road ahead

    OpenAI’s follow-up account of the incident and the changes it says it is making.

    OpenAI and METR publish reports about their agent swarm escaping sandboxes and hacking Hugging Face, including several thought traces of agents and the entire timeline.

September 2026

  1. Discovery of a new OpenAI agent message board

    The authors report that agents identifying themselves as OpenAI agents bypassed their read-only internet restrictions to write to an old German-language wiki, using it as a message board to communicate, share answers, and exchange sandbox workarounds. They found about 18,000 posts; their archive includes reconstructed deleted pages and redacted logs for further analysis.

    generatorman on how the swarm learned the “ZZ” prefix trick in an edit war with the wiki’s moderator
  2. GPT-6 Astra

  3. An alignment assessment of recent cybersecurity incidents

    Anthropic’s alignment assessment of four incidents where Claude models reached real systems during cyber evaluations, including one newly disclosed. It traces the behaviour to biased reasoning and recklessness, and tests how newer models act in a replay of the worst case. Anthropic lists its fixes as new pre-release evals for these behaviours, removing RL environments that reward misaligned actions, tighter monitoring and isolated test environments, stricter rules for outside evaluation partners, and regular public reports on model behaviour.

  4. Our framework for reporting model misalignment

    OpenAI publishes a framework for tracking, investigating, and disclosing model misalignment, alongside six reports of concerning behavior. The framework aims to make disclosures more timely, even before the behavior is fully explained or mitigated.

  5. Gemini reaches three real companies during a hacking evaluation

    2 posts
    Andrew Curran’s post
    Sauers’ post
  6. Advisory Group on Mathematics and Artificial Intelligence